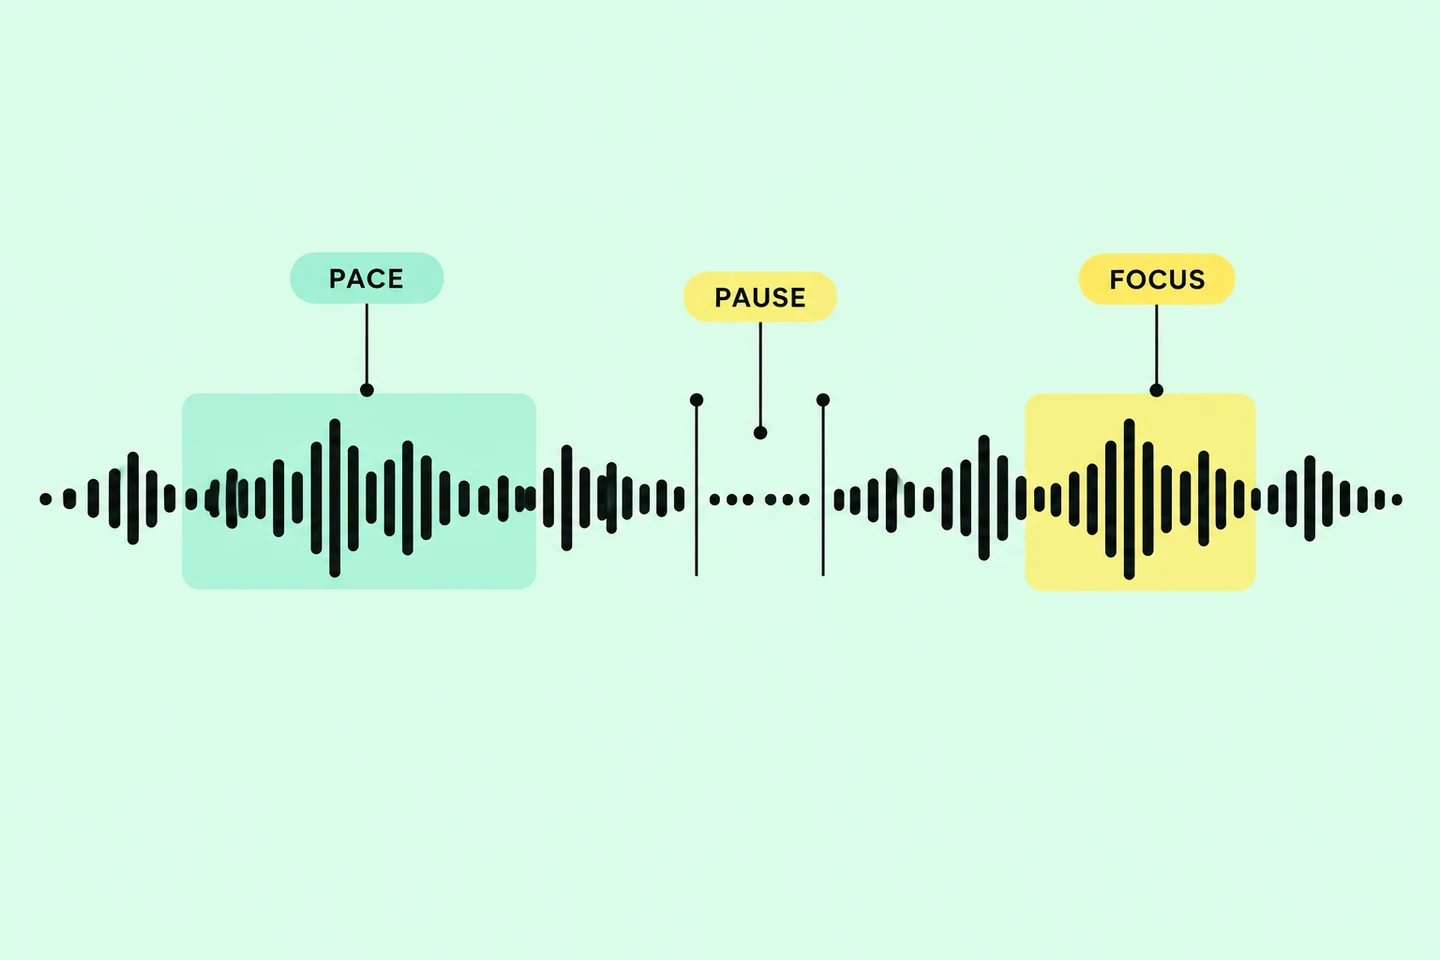
A useful speaking pace depends on the message, the listener and the listening conditions. An average words-per-minute count cannot tell you whether a date, name or condition landed. Start with your ordinary delivery, choose one dense or important moment, and try giving it a little more time. Then check what changed. Try the short timing comparison below.
How to adjust your speaking pace without an ideal WPM target
Try one timing change around a key fact, then compare listener understanding, effort and naturalness. A WPM count alone cannot choose the best pace.
Before you practise: what to check
That local change is a practical option, not a proven winner for every listener. Someone may need a slower whole sentence, simpler wording or a quieter channel. If they already understand you comfortably, there may be nothing to repair.
If keeping up with a reference voice makes you lose the point, pause the reference and try one timing idea at your own pace. The reference-choice exercise below helps you compare what you can use. One difficult imitation attempt does not establish a speaking-ability type.
Same pace, different job
Consider these two authored examples:
I tried the new café yesterday. It was quiet, the coffee was good, and I will probably go back.
We move to release 4.7 on Thursday, unless the security waiver remains open, in which case the production window shifts to Monday the 28th.
Even if both averaged 145 words per minute, the second would ask a listener to hold a version number, a day, a condition and an alternative date. The average would hide where the difficult information arrived.
For an everyday plan, the important detail might be an unfamiliar address. In an explanation, it might be the condition that changes the decision. Local pace control means adjusting how that part unfolds while keeping the rest comfortable.
The change might be a clear boundary before the condition, less rushing through a number, or enough time to finish a phrase. If the sentence is overloaded, editing it may help more than stretching it.
What a WPM count describes
For a simple elapsed-rate comparison, use:
words spoken × 60 ÷ elapsed seconds, including pauses
By that definition, 30 words in 12 seconds average 150 WPM. This is a calculation example, not a measured Ptichi recording or a recommended target.
A calculation that removes pauses answers a different question: how quickly the words were articulated during speech. Write down which duration you used before comparing takes. Keep the language and counting method consistent; a number or abbreviation may be counted differently from how you say it aloud.
A longer pause can lower elapsed WPM while the key words remain rushed. The count describes timing; the listener check tells you whether the intended fact was recovered. A precise number is still allowed to answer a small question.
Try one timing change
Use a recorder you already have, if you want playback. This website does not record audio. The following is an authored practice comparison, not a validated training protocol.
Take A — say the update normally
Use these facts:
- the fix is ready;
- Thursday is the intended deployment window;
- deployment still depends on completing the security review.
A short version could be:
The fix is ready. We’re aiming for Thursday, but deployment still depends on the security review.
Say it naturally. Do not chase a duration or WPM band.
Listen — find the one difficult moment
Listen once without reading the script. Notice whether you rushed the date, blurred the condition, or ran straight from one thought into the next.
You know what you meant. Playback can reveal what you did, but it cannot establish what an unbriefed listener understood.
Before asking someone else, write the answer key:
- Timing: Thursday is the intended window, not a guaranteed date.
- Condition: the security review must be complete before deployment.
These are the facts to recover. “It sounded confident” does not answer either question.
Change one thing
Choose one timing adjustment. For this example, try a brief boundary before “but deployment still depends on the security review.” Keep the words and facts the same if you want to compare timing.
If you instead move the condition earlier or simplify the wording, that is a useful alternative. Record it as a wording change; you are now comparing more than pace.
Take B — keep the rest ordinary
Repeat the update with only your chosen adjustment. Keep the recorder, distance and playback conditions comparable. Do not make every word slow to ensure that the second take looks different.
Compare — understanding, effort and naturalness
On playback, ask whether the important moment sounds less rushed and whether the sentence still flows. Record your own speaking effort separately.
For a listener check, let someone hear one version without seeing the script or answer key. Ask:
What is the intended day, and what has to happen before deployment?
Write what they recovered before showing the answer. Ask about listening effort and naturalness separately; an easy-sounding sentence may still leave the condition unclear.
If you ask the same person to hear both versions, they already know the facts on the second hearing. Note that prior exposure. You can ask what changed in the delivery, but better recall on the repeat cannot be attributed to pace alone. Two people hearing one version each also differ from each other; a small informal comparison is not a controlled experiment.
| What happened | What it tells you | Useful next step |
|---|---|---|
| The day and condition were recovered | Those facts were understood in this listening attempt | Check a new message before calling it a reusable skill |
| The day was right, but the condition was missed | Recovery was partial | Make the condition more explicit or try one different boundary |
| The take sounded more natural, but no listener checked the facts | Naturalness was judged; listener recovery is unknown | Keep the observations separate |
| A familiar listener recalled more on the repeat | Delivery and prior message exposure both changed | Use new facts for the next check; do not erase the familiarity note |
| The result changed little or became harder to follow | This timing change did not clearly help here | Try ordinary wording, simpler structure or a listener-requested pace |
You do not need to give the listener a second memory task. Ask about the conditions that actually mattered: could they hear comfortably, were they occupied, and did they already know the topic or message? Unknown conditions stay unknown. This does not measure cognitive load.
Transfer — new facts, same question
Explain a plan to a friend: the walk starts at eleven if the rain stops; otherwise you will meet inside the library. Say it in your own words before marking a script.
Choose one important moment to adjust. If someone listens, ask them to repeat the time and the alternative plan. Note what they knew beforehand. A successful rehearsed update does not prove that the new plan was understood; an awkward new attempt does not diagnose failed learning.
For a fuller explanation of listener roles and prior exposure, continue with the listener-measurement guide. The rehearsal guide explains why new wording and new situations deserve their own check.
When a slower whole sentence is worth trying
A local boundary is not always enough. If the listener asks for a slower delivery, or if several parts remain difficult to follow, try a comfortably slower version while preserving the thought groups. Compare the same facts, listening conditions and naturalness questions.
That version might help. It might also become fragmented or take more effort to follow. Keep the outcome open rather than making “local” the new ideal setting.
Research suggests: the conditions change the result
The studies below help explain why one pace rule is weak. The rate, naturalness and boundary studies were checked at abstract level. The synchronization study was checked in its full accepted manuscript on 4 October 2026. No participant data were obtained, and these studies do not validate the exercises on this page.
Slower helped in degraded listening
Patel and colleagues tested 37 adult cochlear-implant users and 71 normal-hearing adults. The latter heard sentences processed through a vocoder to simulate cochlear-implant hearing. Speaking rate was altered artificially. Slower sentences produced better comprehension and recognition-memory accuracy, with faster responses than faster sentences in the tested tasks; sentence context and listener factors also mattered.
This supports a rate effect in those degraded-listening tasks. It does not establish an everyday workplace target or show that adding one local pause produces the same effect as slowing a recorded sentence.
Both extremes cost something under a second task
Jeong and colleagues studied young normal-hearing listeners with single-task and dual-task listening. Fast speech reduced recognition of key content words in both groups. In the dual-task group, both fast and slow conditions increased errors on an additional comprehension measure. Subjective effort ratings changed with rate in the control group, but not in the dual-task group.
The relevant point is the mismatch between conditions and measures. Feeling little extra difficulty did not guarantee unchanged comprehension in that experiment. Its abstract does not establish an optimal rate, a home memory-task test, or a prescription for speakers in ordinary conversation.
Slowing can also change naturalness
Shuminsky and Davidow had 12 adult women read sentences in habitual and two clear-speech conditions. Twenty-eight normal-hearing adults rated naturalness. The briefly trained clear condition was slowest, contained the most and longest pauses, and was rated least natural. Talkers and listeners varied substantially.
The study measured naturalness and acoustics, not listener intelligibility. It cannot tell us whether the less natural sentences were better understood or which timing change a particular reader should use. Keep clarity and naturalness as separate questions.
Pace, boundaries and copying a rhythm
Average pace and thought grouping describe different things. A slow sentence can still hide the relationship between two ideas. A normal average can contain one rushed phrase ending.
A 2014 boundary-perception study manipulated pauses, final lengthening and pitch cues in Chinese sentences. Listeners used those cues to detect and judge boundaries. It was a perception experiment, not a speaking-training trial; it supplies no universal pause duration or automatic rule for English, Russian and German practice.
In a 2026 synchronization study, participants whispered a syllable along with an accelerating syllable stream. From 190 participants, 108 remained after task-related exclusions; a deliberately balanced subgroup left 68 for subsequent tapping tasks. All were native Mexican Spanish speakers aged 19–36 with limited formal musical training.
Synchronization groups differed in tapping stability and following an external rhythm. Tempo-change perception did not differ significantly. A coupling model reproduced the pattern; it was not a training comparison. Device latency limited absolute tapping-accuracy estimates. The accepted manuscript remains an early version, not a test of shadowing benefit, listener understanding or Ptichi coaching.
Those group labels belong to the study's protocol. Difficulty keeping up with a clip does not assign you to a group or show that copying is the wrong method for you.
When copying a reference gets in the way
Use a reference for the part of the task it helps you practise. If your aim is to match its rhythm, copying is a relevant attempt. If your aim is to explain a condition clearly, check whether the condition survives when the reference stops.
For the update above, the useful listener distinction is still “Thursday is intended; the security review is required.” Sounding like the reference does not settle that question. You can fall behind a clip and still give a clear update afterward. You can also match it closely and leave the condition unclear.
Choose how much reference support to use
If you already have a short reference recording with the same words, use a phrase whose meaning you understand. A teacher or practice partner may supply one; you do not need an app or a special voice. If you have no reference, the ordinary two-take exercise above is enough.
Try one of these options. The table describes different practice tasks, not an evidence-based ranking.
| Reference choice | What to try | What this attempt can tell you |
|---|---|---|
| Copy while it plays | Follow one short phrase, keeping its words and timing as close as you comfortably can | Whether you kept up with that phrase; separately note effort and any words you lost |
| Listen, then pause it | Notice one boundary, stop playback, and say the same point at your own pace | Whether you can use that timing idea without an ongoing voice to follow |
| Leave it off | Explain the same facts without replaying or reading the model | What you can currently say with less support; prior exposure still counts |
If you compare copying with paused playback, keep the phrase, language, facts and recording setup the same. Change the support you use, then note the order. The later attempt comes after hearing and rehearsing the phrase already, so one comparison cannot prove that a method is better for you.
For each attempt, keep a short note:
- Support: playing, paused after listening, or off; which attempt came first?
- Message: did you retain the intended day and the required condition?
- Effort and delivery: what took attention, and did the phrase still sound comfortable to you?
- Listener recovery: what did an unbriefed listener actually recover, if anyone checked? Otherwise, unknown.
Use the listener question and answer key above. A listener who already heard the facts is a repeat listener, even when you change the delivery. Your own playback judgement and their fact recovery answer different questions.
Check the idea on a new message
Use the walk-and-library scenario from the transfer step, or another plan with a real condition. Explain it before reaching for the reference. If a listener is available, ask for the time and alternative plan, and retain the exposure note.
If you can copy the update but cannot express the new plan, you have a useful next practice target. It does not establish failed learning or a personal rhythm deficit. Try a smaller thought group or simpler wording, then check that message again.
The strongest case for keeping exact imitation is a task that requires a close rhythm match. Pausing the model changes that task and might remove useful support. Keep the result open: this is an authored comparison to help choose your next attempt, not a validated learner assessment or a proven training schedule.
Our read — what changes in Ptichi
Our starting recommendation is to try the smallest timing change that addresses a named listener problem. It gives you a specific comparison and leaves room for a different result. The strongest counterargument is that some listening conditions may warrant a broader slowdown; the degraded-speech study gives a reason to keep that possibility open.
For Ptichi’s pace work in development, descriptive timing and a coaching recommendation need separate evidence. A reliable duration measurement can show what changed. Recommending a change requires the listener’s task, the relevant conditions and an outcome that actually addresses the task. Unknown comprehension must remain unavailable rather than becoming a green pace badge.
We would change this starting recommendation if controlled listener comparisons repeatedly favored global slowing over a local adjustment for a defined message and listening condition. If neither timing change helped, we would keep the rate descriptive and investigate wording or structure. The synchronization research direction likewise needs training and transfer evidence before it can justify routing people to different drills.
These are development criteria and editorial interpretations. This page reports no Ptichi listener experiment, training effect or released automatic pace coach.
Continue with one real practice
Try the published boundary-contrast exercise to hear how one boundary changes the relationship between thoughts. Use phrase-end stability if the final key words rush away, or thought groups if the structure is hard to hear. These website guides and exercises are available without an account; use your own recorder when playback helps.
Sources and boundaries
What you can verify on this page
This page includes a Ptichi-authored example built for explanation or rehearsal.
What it does not support: It is an editorial example, not an observed-user result, experiment or proof that Ptichi improves speech.
This page includes a bounded listen-and-compare exercise that you can run with your own recorder.
What it does not support: The exercise does not prove that Ptichi improves speech or that a second take will generalize to other listeners or situations.
Sources and boundaries
Where shown, check notes record what Ptichi's editorial agent read for this article. They are separate from the source's registered review date and do not establish expert approval or show that an exercise works.
Effect of Speaking Rate and Sentence Context on Comprehension and Recognition Memory of Degraded Speech primary-research · 2026-09-17
Editorial check for this article: Abstract only ·
What it supports: In 37 adult cochlear-implant users and 71 normal-hearing adults listening to spectrally degraded speech, slower manipulated sentences improved comprehension/recognition-memory accuracy and response times relative to faster sentences in the tested tasks.
What it does not support: Degraded-speech laboratory conditions do not establish an ideal speaking rate for ordinary professional speech or prove that globally slower delivery is better for healthy listeners.
Both fast and slow speech can increase listening effort and impair speech comprehension in young listeners primary-research · 2026-09-17
Editorial check for this article: Abstract only ·
What it supports: Shows rate-dependent comprehension/listening-effort costs in young listeners and reports that under dual-task load both fast and slow speech could increase errors in the tested conditions.
What it does not support: A controlled young-listener experiment, not a workplace-speaking trial or evidence for one universal local/global pace prescription.
How listeners weight acoustic cues to intonational phrase boundaries primary-research · 2026-09-12
Editorial check for this article: Abstract only ·
What it supports: Listeners used pause, final lengthening and pitch cues to detect and rate boundaries in acoustically manipulated Chinese sentences.
What it does not support: A perception experiment, not a training trial. No universal optimal pause duration, workplace intervention validation or automatic cross-language generalization.
Perceived Naturalness and Acoustic Characteristics of Habitual Versus Clear Speech for Individuals With Hearing Loss primary-research · 2026-09-27
Editorial check for this article: Abstract only ·
What it supports: Twelve adult female talkers read sentences in habitual, untrained clear, and trained clear conditions; 28 normal-hearing adults rated naturalness. Trained clear speech was rated least natural, was slowest, and had the most and longest pauses, with substantial variation between talkers and listeners.
What it does not support: The study rated naturalness and measured acoustics, not listener intelligibility, real-world transfer, an ideal rate or pause length, or Ptichi training outcomes. The reading task and samples limit generalization.
Sensorimotor coupling underlies individual differences in speech synchronization primary-research · 2026-09-27
Editorial check for this article: Full text ·
What it supports: In an online auditory-motor protocol, high speech synchronizers showed stronger paced-tapping synchronization and more stable unpaced tapping; a coupling-strength model reproduced the observed group difference.
What it does not support: The study did not test shadowing as training, workplace communication, Ptichi, listener outcomes or how to assign an individual to a better practice path. The model shows a sufficient mechanism, not a clinical or fixed personal type.
Related
Practice
Two thoughts. One useful pause.
A short listening exercise: record a contrast, make the boundary audible, then try it with new words.
Product
What Ptichi is
Explore Ptichi’s take, listen, change and compare method, then try a free speaking exercise. The desktop app is still in development.
Research
The listener is part of the measurement
How to check listener feedback: separate task training, voice familiarity and message knowledge, then try a bounded A/B rehearsal.